The Advancements in Natural Language Processing for Translation and Communication
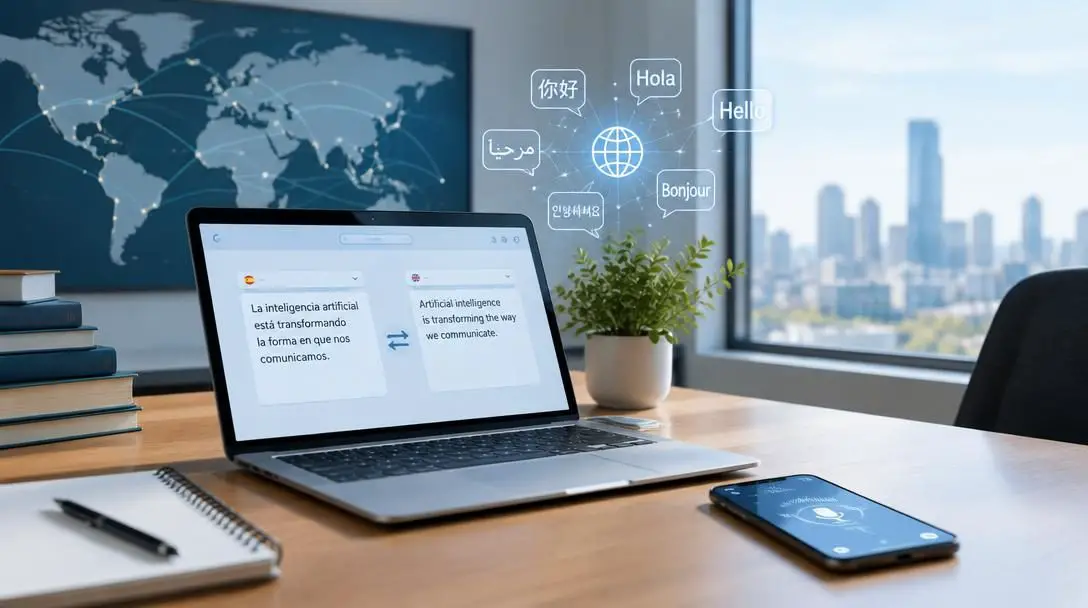
Natural language processing, broadly known as NLP, represents one of the most vital frontiers in artificial intelligence by focusing on the complex computational interaction between computers and human language. Instead of requiring people to bridge the gap with rigid programming scripts or synthetic commands, modern NLP empowers computing systems to understand, interpret, and generate human language in ways that are intuitive, context-aware, and grammatically fluid. Among its diverse capabilities, the advancement of translation and international communication stands out as a defining milestone, reshaping how knowledge, culture, and commerce circulate across global borders.
The journey from early mechanical translation to contemporary deep learning represents decades of architectural breakthroughs. Today, sophisticated neural networks analyze subtle linguistic structures, tone, and context, effectively automating tasks that once required exhaustive manual human effort. As organizations and individuals communicate across multiple languages in real time, understanding the mechanisms, architectures, practical workflows, and potential hazards of NLP has become essential for anyone navigating the modern information landscape.
Key takeaways
- Natural language processing has transitioned from rigid rule-based programming to data-driven statistical models, and finally to context-aware deep neural networks.
- Modern architectures like BERT, GPT-3, and Transformer-XL analyze complex contextual relationships across words rather than translating text in isolated fragments.
- Advanced language technologies power critical communication workflows, including machine translation, speech transcription, sentiment analysis, and interactive virtual assistants.
- Successful implementation demands rigorous quality benchmarks and human oversight to prevent inaccuracies, cultural misunderstandings, and linguistic biases.
The Evolutionary Path of Machine Translation
The technical methodologies underpinning automated translation have undergone profound conceptual shifts over the past several decades. To appreciate how modern conversational systems achieve human-like expression, it is necessary to examine the foundational paradigms that preceded them.
The earliest computational efforts emerged during the 1950s under the framework of Rule-Based Machine Translation. Computer scientists attempted to codify human linguistics explicitly by programming dictionaries and hard-coded grammatical rules into machines. While this pioneering approach proved that computers could perform linguistic substitutions, it quickly encountered practical dead ends. Human communication is inherently fluid, packed with idioms, regional dialects, irregular grammatical exceptions, and shifting contextual subtleties that static dictionaries and rigid conditional statements simply cannot capture.
By the 1990s, the field experienced a major breakthrough with the development of Statistical Machine Translation (SMT). Rather than relying on human engineers to hand-craft linguistic rules, SMT engines analyzed massive digital archives of bilingual text to calculate the mathematical probability that a specific word or phrase in one language corresponded to another. This statistical approach produced vastly superior translation outputs compared to its rule-based ancestors. However, SMT models still evaluated text in isolated chunks or short phrases. As a result, they frequently failed when dealing with long-range sentence restructuring, producing output that felt fragmented, awkward, and syntactically unnatural.
The contemporary era began with the arrival of Neural Machine Translation (NMT). Rather than processing text in disjointed fragments, NMT employs multi-layered deep neural networks capable of evaluating entire sentences simultaneously. By processing sentences holistically, neural networks map complex, multi-dimensional relationships between words and overarching semantic concepts. This structural leap has dramatically enhanced grammatical fluency, contextual comprehension, and stylistic consistency across automated translation systems.
Breakthrough Model Architectures Transforming NLP
At the center of today's natural language processing ecosystem are large-scale neural language models trained on massive corpuses of digitized text. Unlike earlier architectures, modern transformer-based systems can dynamically examine how the presence of one word influences the meaning of every other word across an entire passage. Three foundational architectures have played an outsized role in expanding these capabilities.
BERT
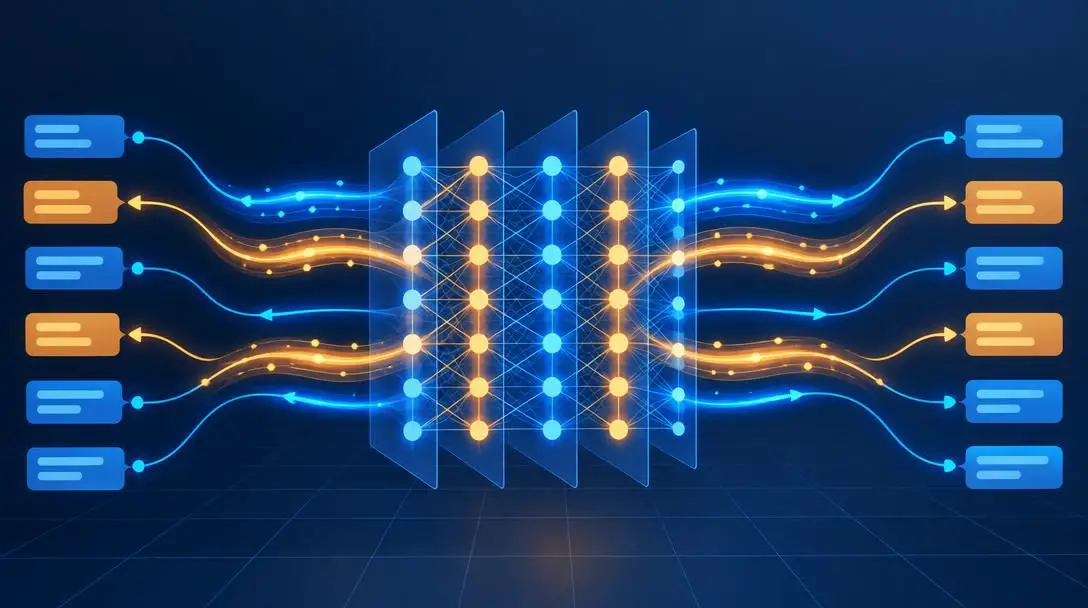
- Developer: Google
- Core Architecture: Bidirectional Transformer Encoder
- Primary Strengths: Bidirectional context evaluation, question answering, sentiment analysis
Developed by Google, BERT—short for Bidirectional Encoder Representations from Transformers—fundamentally transformed how algorithms interpret written passages. Prior transformer implementations tended to read text sequentially from left to right or right to left. BERT broke this limitation by scanning words bidirectionally, evaluating the contextual environment of a target word from both sides simultaneously. This deep bidirectional perspective makes BERT exceptionally capable across interpretive tasks such as question-answering engines, cross-lingual retrieval, and sentiment classification.
GPT-3
- Developer: OpenAI
- Core Architecture: Autoregressive Transformer
- Primary Strengths: Natural text generation, conversational fluency, low-resource language processing
Developed by OpenAI, GPT-3 (Generative Pre-trained Transformer 3) is a massive autoregressive language model celebrated for its capability to generate fluid, coherent, and contextually rich text. By training across expansive linguistic datasets, GPT-3 excels in generative tasks, including interactive conversational agents, text autocompletion, automated writing, and cross-border translation. A significant advantage of GPT-3's comprehensive generative capacity is its utility in bridging communication for low-resource languages—dialects and languages that possess minimal digitized training data compared to dominant global languages.
Transformer-XL
- Developer: Google
- Core Architecture: Extended Context Transformer
- Primary Strengths: Long-term dependency retention, long-form modeling, extended document translation
Developed by Google, Transformer-XL was engineered directly to resolve a significant bottleneck in natural language models: the architectural memory limits that constrain context windows. Standard transformers struggle when tracking narrative threads or semantic continuity across extended documents. Transformer-XL integrates recurrence into its attention mechanisms, enabling the network to learn long-term dependencies across long passages without losing context. This makes it an essential engine for long-form textual modeling, technical document localization, and extended machine translation tasks.
| Model Architecture | Developer | Processing Focus | Key Translation and Communication Advantage |
|---|---|---|---|
| BERT | Bidirectional contextual encoding | Superior contextual comprehension and sentiment nuance across sentences | |
| GPT-3 | OpenAI | Autoregressive generative modeling | Fluent, human-like generation and accessibility for low-resource languages |
| Transformer-XL | Recurrence-based long-term context retention | Sustained contextual coherence across extensive, long-form documents |
Core Applications Powering Modern Communication
The practical utility of natural language processing extends far beyond theoretical laboratory models. Modern deep neural networks actively power critical communications across global industries, international governance, and everyday human interaction.
High-quality machine translation engines now operate as foundational infrastructure for global exchange. In international diplomacy, automated translation tools allow state bodies to analyze and comprehend cross-border communiqués instantaneously. In commercial enterprise, these engines accelerate international commerce, localize marketing campaigns, and ensure reliable coordination across disparate supply chains. In education, automated translation acts as an interactive learning partner, enabling students to explore foreign literature and scholarly texts with minimal friction.
Parallel advancements in speech recognition and transcription have closed the divide between spoken audio and written documentation. By transcribing human speech in real time, speech processing engines power accessibility tools, live closed captioning for international broadcasts, real-time conference transcription, and voice dictation software. These tools break down communication barriers across diverse accents and regional dialects, translating verbal discourse into searchable text.
Organizations also lean heavily on sentiment analysis to interpret the tone, emotional disposition, and attitude conveyed in human writing. Marketing teams use sentiment monitoring to gauge consumer perception across multilingual social forums, while political and sociological researchers monitor public responses to major policy announcements and international events. Rather than relying on simple keyword counts, modern sentiment systems understand irony, dissatisfaction, and enthusiasm in context.
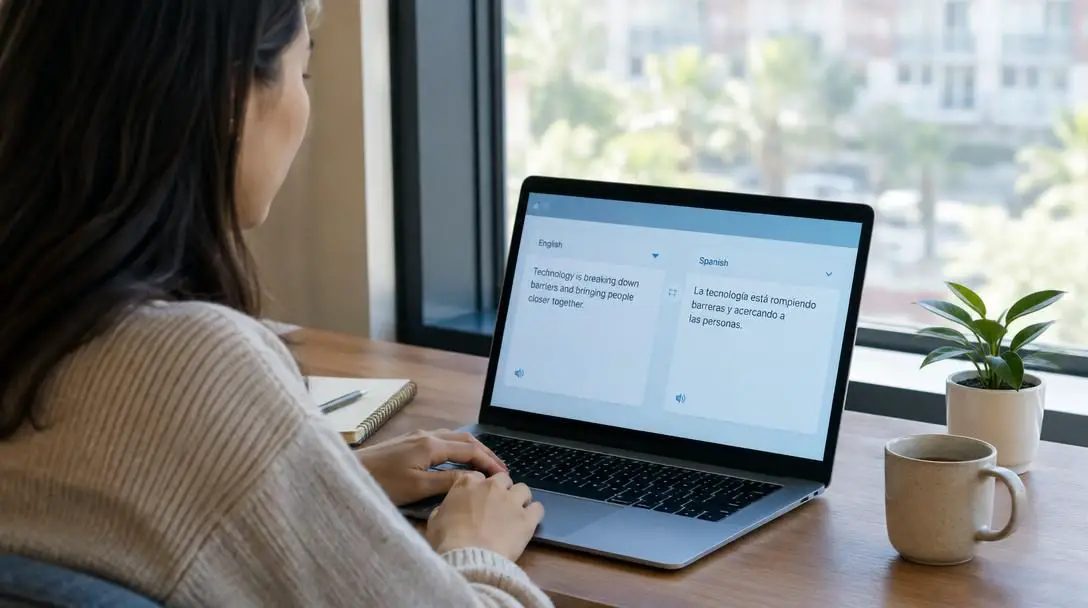
Finally, chatbots and virtual assistants have transformed front-line communication in customer support, technical assistance, and sales. By combining contextual language interpretation with real-time text generation, automated agents guide users through troubleshooting protocols, answer complex account inquiries, and handle repetitive transactions. This frees human personnel to focus on higher-level, empathetic, and sensitive matters.
Advanced neural networks have transformed machine translation from a clumsy exercise in word substitution into a nuanced discipline of contextual interpretation.
How to Implement Natural Language Tools: A Step-by-Step Guide
Deploying natural language processing applications requires a structured deployment strategy. Whether an organization is implementing internal sentiment monitoring or integrating an outward-facing translation engine, following disciplined procedural steps ensures operational stability and factual precision.
- Define the Communication Objective: Determine the precise operational challenge you intend to solve. Clarify whether your application requires direct foreign-language translation, voice-to-text audio transcription, customer-facing conversational support, or internal brand sentiment tracking.
- Audit and Select Available Data: Review internal text corpora, customer interaction logs, and documentation. Assess whether the deployment targets high-resource languages with abundant linguistic data or low-resource languages that require broad generative models like GPT-3 to bridge documentation deficits.
- Choose the Appropriate Architecture: Select the foundational framework that best fits your functional requirements. Deploy bidirectional architectures like BERT for sentiment classification and targeted comprehension tasks, leverage Transformer-XL for extended context and long-form translation, or utilize generative models for interactive conversational workflows.
- Establish Quality Benchmarks: Build clear evaluation criteria to test system performance before exposing it to users. Assess candidate models on grammatical accuracy, specialized terminology consistency, emotional tone, and factual fidelity.
- Incorporate Human Oversight: Implement a robust human-in-the-loop workflow. While advanced neural architectures generate remarkably fluent language, designated human reviewers must routinely audit machine outputs, correct contextual errors, and handle anomalous edge cases.
Common Pitfalls and Challenges in NLP Deployment
While natural language tools offer undeniable operational efficiency, relying on them without adequate safeguards introduces significant risks. Organizations routinely stumble when navigating the subtleties of automated text processing.
- Assuming Fluency Equals Factual Accuracy: Generative models and neural translation systems often construct beautifully phrased, grammatically spotless sentences that are entirely incorrect. Treating conversational fluency as an indicator of factual truth is a dangerous operational error.
- Neglecting Language Ambiguity and Cultural Nuance: Natural human communication is rich with humor, local colloquialisms, regional double meanings, and historical idioms. Deploying machine translation tools without local linguistic vetting can produce embarrassing, confusing, or culturally offensive outputs.
- Over-Relying on Uncurated Training Data: Machine models inevitably mirror the flaws, prejudices, and errors embedded within the datasets used to train them. Training models on raw, unvetted web data can perpetuate severe social biases and distort analytical conclusions.
- Ignoring Low-Resource Constraints: Translation quality varies significantly across languages. While engines perform with exceptional precision on languages heavily represented on the internet, they struggle with low-resource languages, requiring targeted prompt engineering or alternative data strategies.
- Overlooking Systemic Deception and Security Risks: Because modern language models produce human-like text effortlessly, bad actors can exploit them to generate persuasive misinformation, forge communications, or manipulate automated conversational agents.
Addressing Context, Culture, and Ethical Boundaries
As natural language processing continues to mature, researchers and practitioners face fundamental architectural and ethical hurdles. The primary technical bottleneck remains the deep problem of situational context and ambiguity. Models such as BERT and Transformer-XL have significantly widened comprehension windows, yet software remains fundamentally detached from the physical world. Human conversation relies heavily on unwritten social contracts, unspoken physical cues, and shared cultural histories that algorithms cannot observe. Solving this requires ongoing innovation in deep neural design and broader representation for under-indexed languages.
Simultaneously, the widespread availability of human-level text generation demands comprehensive ethical accountability. When computational systems mimic human correspondence with indistinguishable fluency, institutions bear the responsibility of safeguarding users against manipulation, unauthorized impersonation, and automated deception. Constructing transparent, auditable natural language pipelines is essential to ensure that global communication technologies remain secure, inclusive, and fundamentally trustworthy.
Frequently asked questions
How does Neural Machine Translation differ from Statistical Machine Translation?
Statistical Machine Translation relies on mathematical probabilities derived from bilingual text databases and translates text in isolated phrases or word chunks. In contrast, Neural Machine Translation uses multi-layered deep neural networks to evaluate entire sentences simultaneously, resulting in superior grammatical fluency, holistic context recognition, and more natural expression.
What makes BERT's bidirectional processing unique?
Traditional language models typically read text in a single direction, either left-to-right or right-to-left. Google's BERT processes text bidirectionally, evaluating the words that appear before and after a target word at the same time, which gives it a far deeper contextual grasp for comprehension tasks and sentiment analysis.
Why is GPT-3 particularly useful for low-resource languages?
Low-resource languages lack the vast digitized text databases available to dominant languages. GPT-3's broad, pre-trained generative architecture allows it to apply generalized language modeling capabilities to generate coherent text and support translation tasks even when training data in a specific language is limited.
How does Transformer-XL handle long passages of text?
Standard transformer models have rigid context windows that struggle to retain memory across lengthy documents. Transformer-XL resolves this architectural constraint by integrating recurrence into its attention mechanisms, enabling the system to maintain contextual continuity and evaluate long-term dependencies across extended passages.
Why is human oversight still necessary if neural models produce fluent text?
Modern language models can generate grammatically flawless prose that contains factual falsehoods, subtle cultural offenses, or distorted meanings. Human-in-the-loop workflows are critical to catch linguistic edge cases, verify technical accuracy, and ensure appropriate cultural nuance.
The bottom line
The progression of natural language processing from rule-based substitution engines to context-aware deep neural networks represents a monumental leap in artificial intelligence. Systems powered by architectures such as BERT, GPT-3, and Transformer-XL have transformed global communication, breaking down linguistic silos across international commerce, scientific research, and day-to-day conversation. Yet technology alone cannot navigate the subtle complexities of human thought. By pairing cutting-edge neural architectures with rigorous human oversight, cultural mindfulness, and strict ethical standards, organizations can build communication bridges that are not only technologically advanced, but authentically reliable and universally accessible.