The Intersection of Computing and Biology: An Overview of Computational Biology
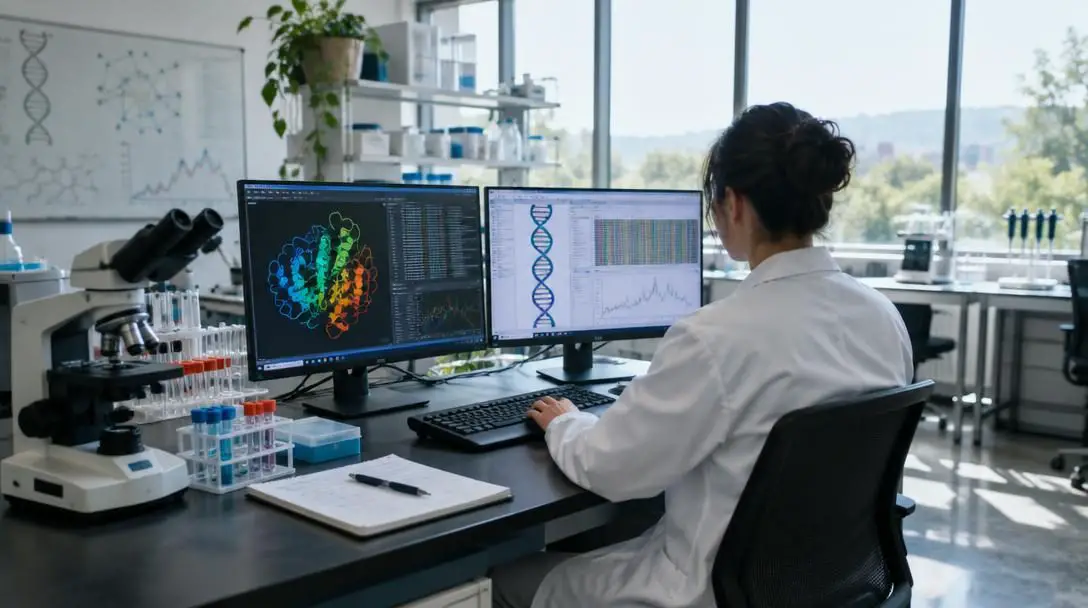
In traditional scientific research, biological systems were studied almost exclusively through manual laboratory experimentation, direct physical observation, and laborious calculations. Today, the life sciences generate such an overwhelming volume of complex biological data that human observation alone is no longer sufficient. High-throughput laboratory equipment, automated assays, and modern molecular tools yield massive datasets of genetic sequences and physical measurements every day.
Computational biology has emerged as an essential disciplinary bridge connecting computing, mathematics, and biological science. By transforming raw biological signals into structured digital representations, this quantitative field allows scientists to decode the mechanisms of life across multiple scales, ranging from microscopic subatomic molecular interactions to vast macroscopic ecosystems.
Key takeaways
- Computational biology bridges physical biological experimentation with computational and mathematical modeling to process vast amounts of life sciences data.
- Core methodologies such as genome sequencing, sequence alignment, phylogenetic analysis, protein structure prediction, and molecular dynamics simulations reveal structural, functional, and evolutionary insights.
- The standard scientific pipeline moves from physical wet-lab digitization to algorithmic computation, followed by empirical laboratory validation.
- Cross-industry applications span targeted pharmaceutical discovery, customized healthcare treatments, high-yield agriculture, industrial bioengineering, and ecological monitoring.
- Major hurdles include substantial computing power demands, massive data storage requirements, multi-omic data integration, and critical ethical concerns surrounding genetic privacy.
Core Techniques in Computational Biology
Modern computational biology relies on a specialized toolkit of algorithmic methods to analyze biological materials at varying structural, functional, and temporal resolutions. These core computational approaches enable researchers to read the underlying genetic blueprints of life, trace evolutionary lineages, and simulate physical atomic behavior directly inside a computer.
Genome Sequencing
Genome sequencing is the foundational process of cataloging the precise order of nucleotides across an entire organism's DNA. By identifying the exact nucleotide sequence—the foundational building blocks of adenine, thymine, cytosine, and guanine—sequencing provides an accurate molecular baseline of an organism's complete genetic makeup. This digital baseline serves as the starting point for nearly all subsequent biological inquiry, genetic engineering, and comparative genomics.
Sequence Alignment
Sequence alignment directly compares two or more DNA, RNA, or amino acid sequences against one another to identify regions of similarity and divergence. By detecting conserved elements across species or individuals, computational researchers can locate critical functional domains, infer evolutionary homology, and extract meaningful functional insights from newly discovered, uncharacterized genetic fragments.
Phylogenetic Analysis
Phylogenetic analysis models evolutionary history by organizing genetic and biological variation into branching evolutionary trees. By calculating degrees of sequence divergence and statistical similarity among related organisms, this technique traces common ancestry, clarifies taxonomic relationships, and tracks how modern biological traits emerged across distinct lineages over millions of years.
Protein Structure Prediction
Proteins are composed of linear chains of amino acids that fold into intricate three-dimensional shapes to perform their biological functions. Protein structure prediction computationally deduces this spatial 3D architecture directly from the primary one-dimensional amino acid sequence. Deciphering this physical geometry is vital for uncovering enzymatic activity, understanding cellular pathways, and engineering precision pharmaceuticals that dock precisely into receptor binding pockets.
Molecular Dynamics Simulation
Going beyond static structural models, molecular dynamics simulation applies fundamental physical laws to calculate the forces acting on every atom over time. This technique provides continuous, atomic-level movies of macromolecules such as proteins and nucleic acids as they shift, flex, and interact within simulated biological environments. Researchers rely on these simulations to observe transient conformational changes and predict how potential drug compounds physically bind to moving biological targets.
| Technique | Primary Input Data | Core Analytical Objective | Key Scientific Output |
|---|---|---|---|
| Genome Sequencing | Physical DNA and biological tissues | Determine precise nucleotide order | Comprehensive organismal genetic blueprints |
| Sequence Alignment | Uncharacterized and reference sequence strings | Identify shared regions of identity and variance | Homology maps and conserved functional motifs |
| Phylogenetic Analysis | Comparative genetic and phenotypic datasets | Map lineage trajectories and ancestry | Branching evolutionary phylogenetic trees |
| Protein Structure Prediction | Primary linear amino acid sequences | Determine energetically favorable folding | Digital 3D macromolecular structures |
| Molecular Dynamics Simulation | 3D atomic coordinates and force fields | Simulate atomic movements and binding events | Time-resolved physical conformational trajectories |
How Computational Biology Works in Practice
Computational biology functions through a cohesive, multi-stage operational pipeline that creates an ongoing feedback loop between physical biological matter and dry computational modeling. The workflow translates raw wet-lab biological chemistry into structured, machine-readable datasets that can be algorithmically interrogated.
The operational framework begins with raw biological samples, such as human tissue biopsies, bacterial cultures, or agricultural plant matter. Through high-throughput laboratory technologies such as genome sequencing, these biological components are digitized. This crucial step converts wet-lab chemical phenomena into standardized computational formats, including alphanumeric nucleotide strings, quantitative gene expression matrices, and three-dimensional atomic spatial coordinates.
Once converted into digital files, the data is pushed through specialized analytical pipelines. Sequence alignment programs rapidly query global repositories to locate homologous genes, structural modeling software computes the lowest-energy folding arrangements based on chemical principles, and molecular dynamics tools simulate atomic behavior under simulated physiological conditions. Rather than expending vast physical resources testing chemical interactions by hand, scientists use these dry models to narrow down millions of potential hypotheses into a focused set of viable candidates.
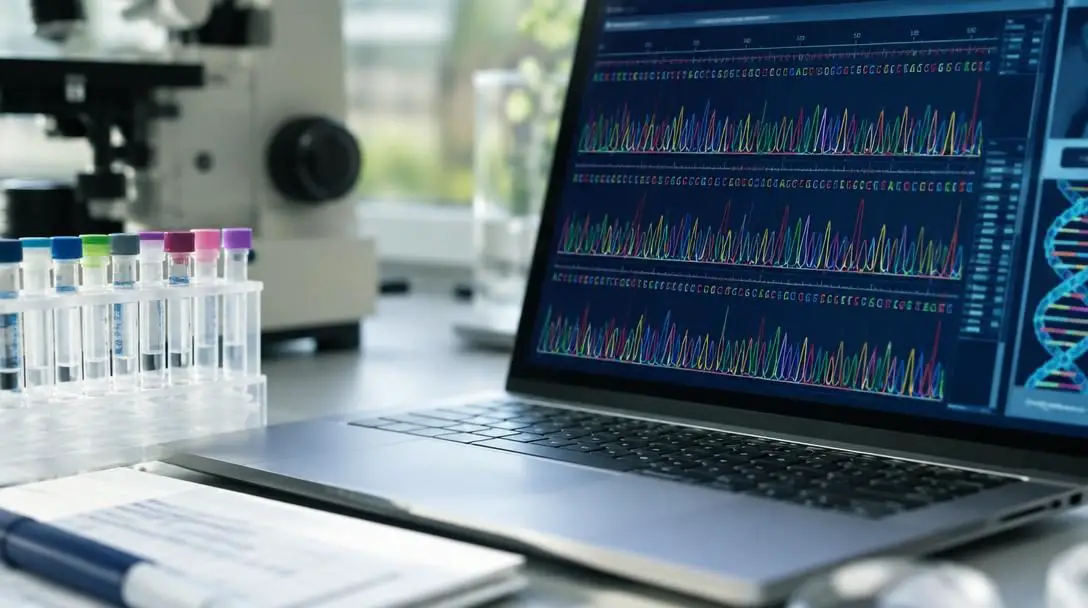
Computational biology transforms raw biological materials into digital coordinates, enabling researchers to explore the fundamental mechanisms of life inside simulated environments.
The digital results are then interpreted to address the initial research hypothesis. Once a high-probability computational candidate is identified—such as an optimized enzyme or a small-molecule drug candidate predicted to inhibit a pathogen—the findings are transitioned back to physical wet laboratories for empirical validation.
Step-by-Step Guide to Applying Computational Biology
Executing an effective computational biology project requires a rigorous, structured approach to ensure biological reproducibility and maintain data integrity throughout the analytical workflow.
- Define the Biological Question: Establish a clear, explicit scientific objective. Determine whether the project seeks to discover a disease-associated genetic mutation, optimize an industrial biocatalyst, or reconstruct ancestral divergence among species.
- Gather and Digitize Data: Extract physical biological samples and digitize them using high-throughput platforms like sequencing machines, or curate established genomic and structural records from public biological databases.
- Preprocess and Clean Biological Data: Remove laboratory artifacts, filter out low-quality sequence reads, correct formatting discrepancies, and normalize expression values so that analytical algorithms receive clean, standardized inputs.
- Select and Apply Analytical Techniques: Match the biological question with the correct computational tools. Run sequence alignments to locate variations, build phylogenetic trees to establish evolutionary history, or execute molecular dynamics simulations to observe dynamic physical behavior.
- Analyze and Interpret Outputs: Evaluate the resulting probability scores, structural configurations, or evolutionary maps. Determine whether the computational evidence effectively addresses the foundational biological hypothesis.
- Validate Through Laboratory Testing: Transfer top computational predictions back to the wet laboratory. Perform targeted physical experiments—such as binding assays or cell culture testing—to verify that digital predictions match physical reality.
Wide-Ranging Applications Across Industries
The tools and analytical pipelines of computational biology drive transformative solutions across multiple commercial sectors and research disciplines, answering critical real-world challenges.
Drug Discovery and Development
Traditional pharmaceutical development requires years of trial-and-error laboratory testing across tens of thousands of chemical candidates. Computational biology accelerates this discovery timeline by digitally identifying viable biological targets, designing novel therapeutic molecules, and simulating compound binding and potential physiological effects before physical synthesis ever begins.
Disease Diagnosis and Treatment
In clinical medicine, computational tools analyze patient sequencing data to detect precise disease-causing genetic mutations. Uncovering an individual patient's unique molecular profile allows medical teams to move past one-size-fits-all treatments and prescribe targeted, personalized therapies designed to address the specific genetic drivers of illness.
Agriculture
Agricultural researchers use computational genomics to sequence and analyze crop and livestock genomes. By identifying genetic markers tied to environmental resilience, pest resistance, and yield efficiency, computational biology enables the rapid breeding and engineering of hardier crops to safeguard global food security in variable climates.
Biotechnology
Industrial biotechnology uses computational design to engineer custom proteins, synthetic biological circuits, and novel enzymes. These tailored biological components optimize industrial chemical synthesis, enable the production of sustainable biofuels, and lower the carbon footprint of manufacturing processes.
Environmental Sciences
Environmental scientists evaluate ecological stability and track biodiversity loss using computational techniques. By modeling species survival, tracking community gene expression, and analyzing how ecosystems respond to chemical pollutants and shifting climates, researchers can formulate evidence-based conservation strategies.
Key Challenges and Limitations
While computational biology offers extraordinary analytical reach, several substantial operational, technical, and ethical bottlenecks continue to challenge the field.
Data management represents an immense ongoing hurdle. The exponential output of high-throughput sequencers produces vast volumes of biological data. Storing, indexing, transferring, and archiving these petabyte-scale repositories requires costly database architectures and robust data-governance standards.
Furthermore, computational power constraints frequently limit research throughput. Atomic-level molecular dynamics simulations and high-resolution phylogenetic analyses require immense processing capacity. Running these computationally demanding models can create significant operational delays, especially when researchers lack access to supercomputing infrastructure.
Ensuring accuracy and reliability remains a persistent concern. Algorithmic approximations, mathematical simplifications, and data noise can introduce subtle biases into digital outputs. If a computational model fails to reflect biological reality, subsequent physical experiments may be fundamentally flawed.
Equally complex is the integration of multiple data types. Biological systems function across interconnected layers. Blending distinct datasets—such as genomic sequences, transcriptomic levels, and phenotypic expressions—demands sophisticated statistical methods to avoid fragmented, misleading interpretations.
Finally, ethical and privacy concerns surround the widespread collection of human genetic information. As individual DNA sequencing becomes common, questions regarding the legal ownership of genetic data, digital consent, and the potential misuse of sensitive biomedical information demand rigorous ethical oversight and protective public policy.
Common Mistakes to Avoid in Research
Coordinating computational algorithms with living biological systems requires avoiding common technical and conceptual errors that undermine experimental success.
- Overlooking Data Quality Controls: Assuming that raw biological data is free of errors is a critical mistake. Skipping quality filtering allows sequence read errors, primer dimers, and sample contamination to propagate downstream, corrupting sequence alignments and structural predictions.
- Treating Software Tools as Black Boxes: Deploying complex computational algorithms without understanding their underlying assumptions and mathematical limitations often leads to misinterpreted findings. Researchers must understand an algorithm's boundary conditions before applying it to novel biological systems.
- Neglecting Data Heterogeneity: Forcing mismatched biological datasets into a unified analysis without appropriate normalization distorts outputs. Genetic, transcriptomic, and phenotypic datasets operate on different mathematical scales and require specialized integration methods.
- Omitting Experimental Validation: Relying exclusively on computational predictions without scheduling wet-lab verification compromises research rigor. Computational models are predictive hypotheses that must always be verified through physical laboratory experiments.
- Disregarding Ethical and Privacy Safeguards: Treating human genetic information merely as numerical data points while ignoring patient privacy and data rights presents serious legal and ethical dangers. Transparent data protection standards must be maintained across all stages of research.
Emerging Frontiers: Personalized Medicine and Synthetic Biology
Computational biology is advancing beyond descriptive analysis toward predictive and constructive applications, driving profound innovations in healthcare and bioengineering.
In personalized medicine, computational frameworks process an individual's unique genetic code, environmental exposures, and lifestyle variables to craft precision medical interventions. Rather than relying on generic, population-wide treatment regimens, physicians can anticipate adverse drug reactions, select therapies targeted to a patient's exact genetic profile, and dramatically improve clinical outcomes.
Simultaneously, the discipline is fueling the growth of synthetic biology. Rather than solely cataloging existing life forms, computational scientists design artificial biological systems from the ground up. By computationally modeling genetic circuits and designing bespoke enzymes, researchers can engineer living cells capable of producing sustainable materials, neutralizing environmental contaminants, or delivering localized therapies directly inside the human body.
Frequently asked questions
What is the difference between bioinformatics and computational biology?
While often used interchangeably, bioinformatics generally focuses on developing software tools, databases, and algorithms to store, organize, and retrieve biological data. Computational biology uses those tools, alongside mathematical and theoretical models, to directly analyze biological systems, simulate physical mechanisms, and answer broader scientific questions.
Why do computational predictions require wet-lab experimental validation?
Computational models rely on mathematical simplifications, calculated force fields, and statistical approximations that cannot account for every environmental nuance inside a living cell. Physical laboratory testing confirms that the predicted molecular bindings, enzymatic speeds, or genetic variations behave accurately within real biological systems.
How does sequence alignment help identify evolutionary relationships?
Sequence alignment compares nucleotide or amino acid sequences across multiple organisms to detect regions of shared identity. High degrees of sequence conservation typically point to functionally critical regions inherited from a common ancestor, enabling scientists to reconstruct evolutionary timelines and assess species divergence.
What role does molecular dynamics simulation play in drug discovery?
Unlike static 3D structures, molecular dynamics simulations show how proteins and target receptors flex, move, and change shape over time. This dynamic atomic view helps pharmaceutical researchers observe how potential drug candidates dock into binding pockets and predict whether a molecule will remain stably bound under simulated physiological conditions.
What are the main privacy concerns associated with computational genomics?
Human genomic data contains highly identifiable, deeply personal information regarding an individual's inherited traits, disease susceptibilities, and familial ties. Ensuring that sensitive genomic files are securely stored, properly anonymized, and protected from commercial exploitation or unauthorized surveillance is a major ethical priority.
The bottom line
Computational biology has transformed the life sciences from a largely descriptive discipline into an analytical, data-driven science. By bridging computer science, applied mathematics, and molecular biology, researchers can decode genetic baselines, simulate intricate atomic interactions, and solve complex challenges in medicine, agriculture, and industry.
As computational processing capacity grows and biological datasets continue to expand, the integration of algorithmic modeling with empirical laboratory research will remain the driving engine of scientific discovery, unlocking deeper insights into the fundamental mechanisms of living systems.